
Cross-Modal and Uncertainty-Aware Agglomeration for Open-Vocabulary 3D Scene Understanding
IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · 2025
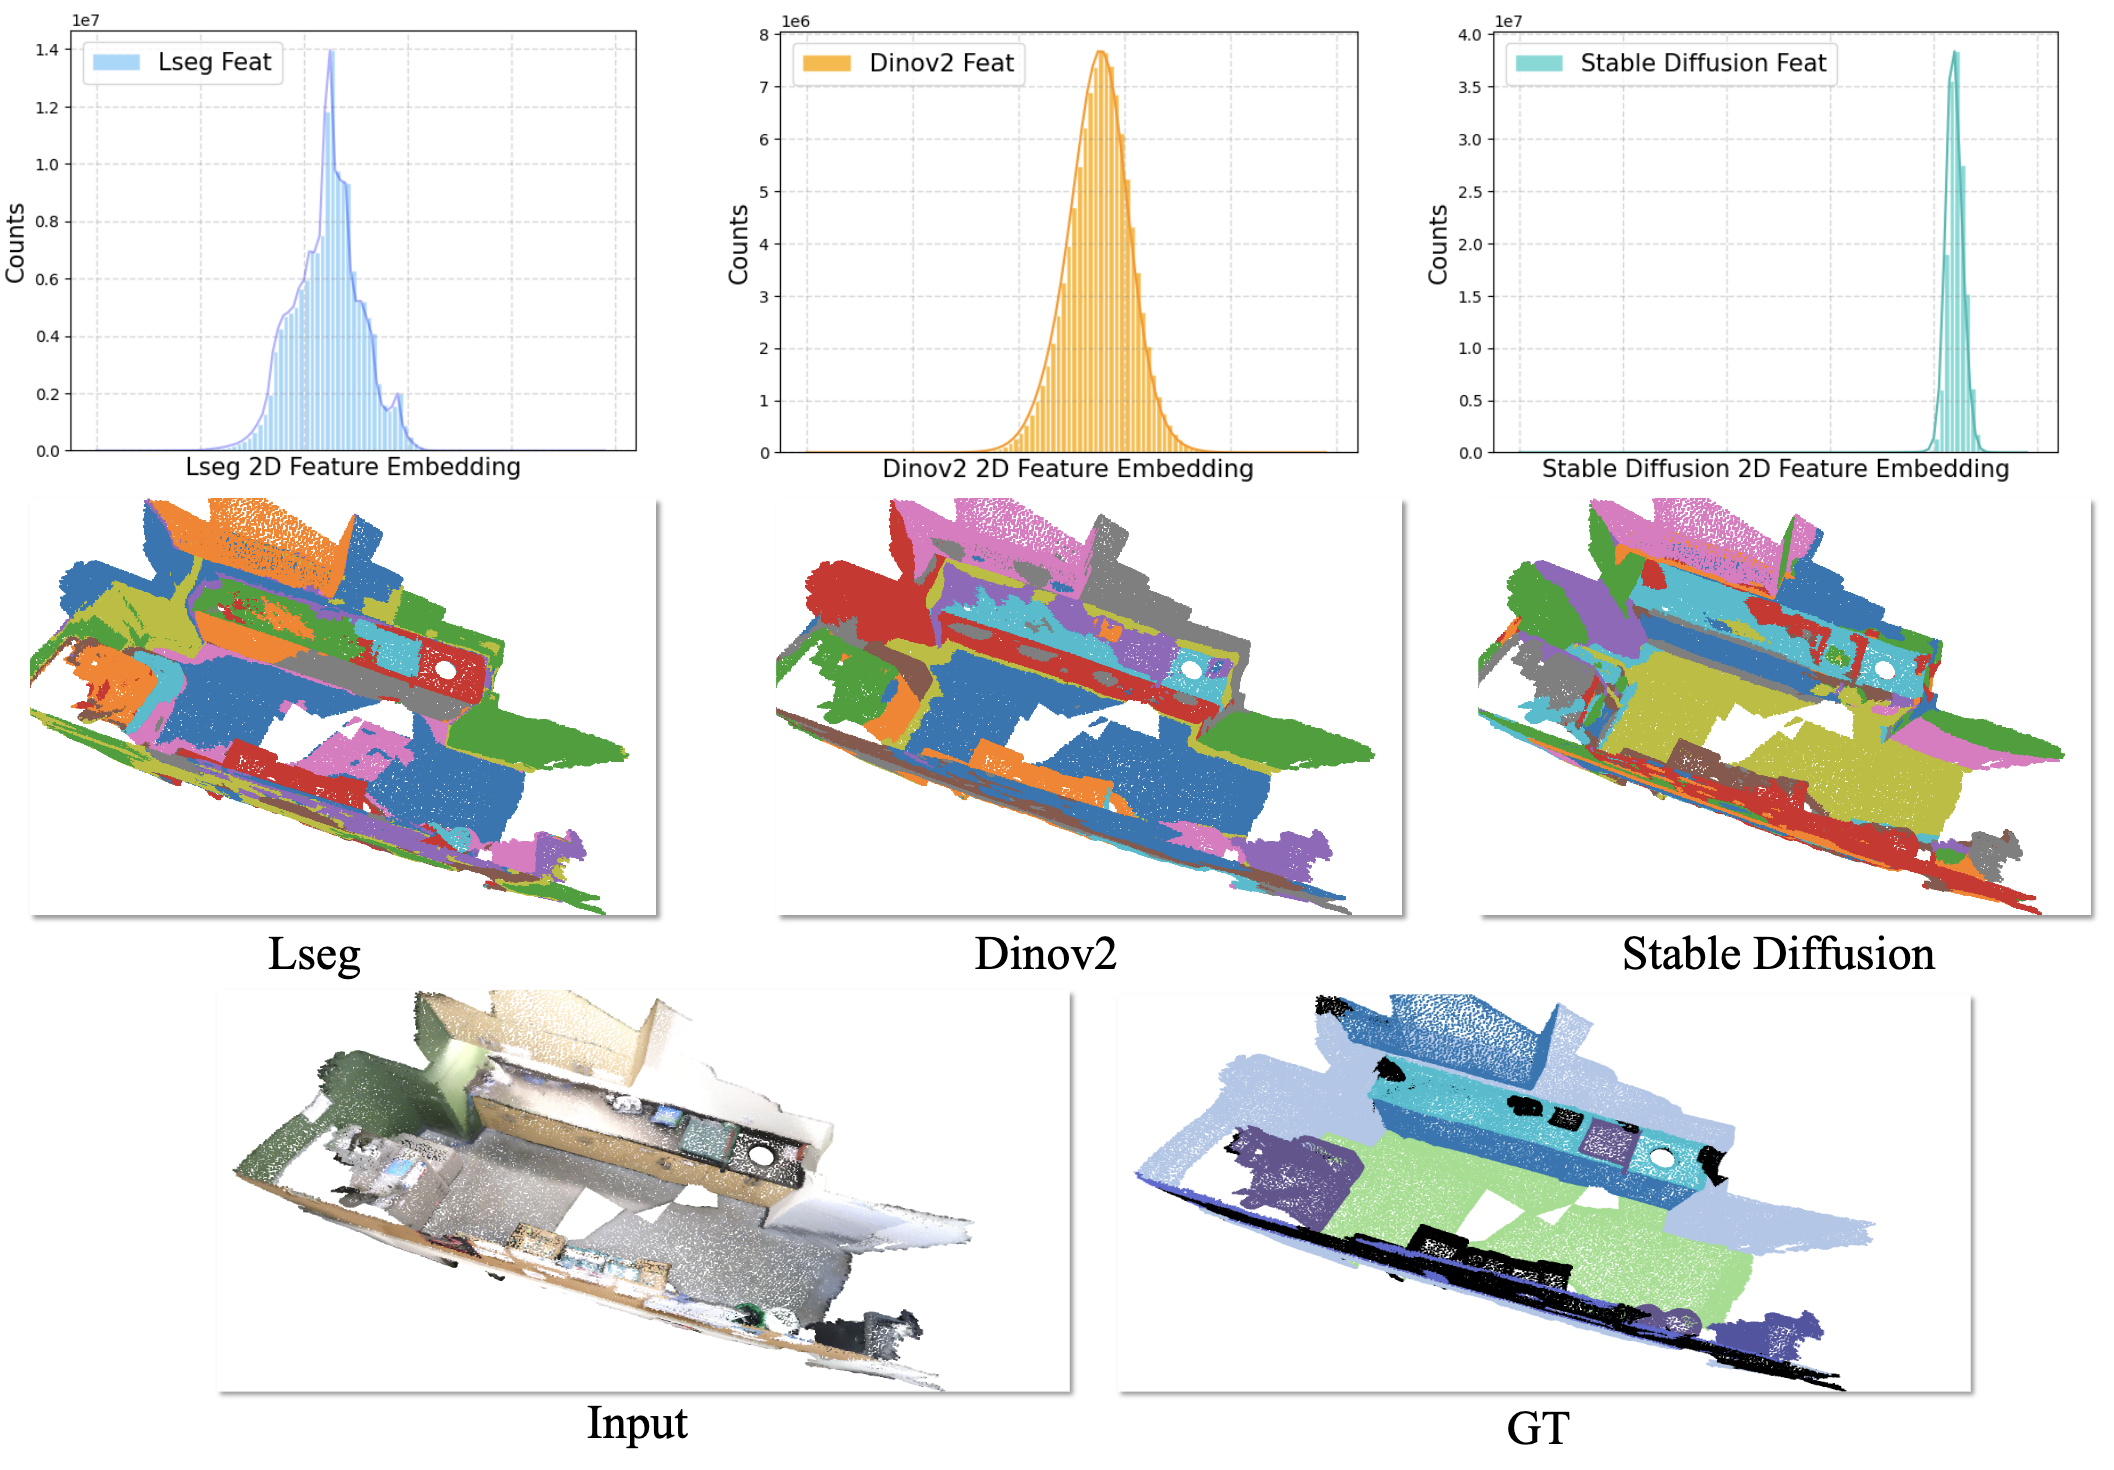
Combining complementary foundation models with uncertainty-aware distillation for 3D scene understanding.